
USE CASES
Infrastructure built around the workload.
AALTA Infrastructure provides dedicated compute environments for model training, large-scale inference, private AI systems and long-term GPU capacity growth.
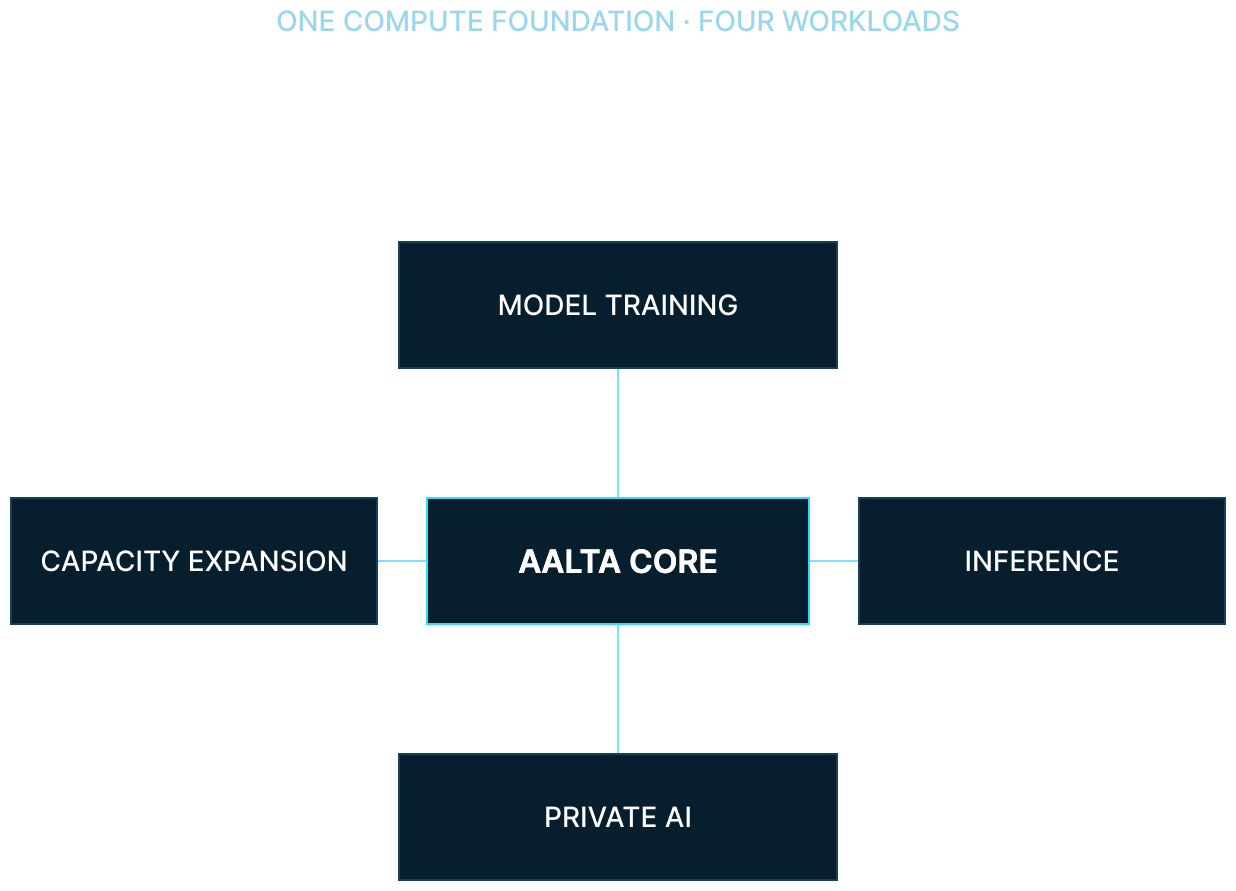
ONE FOUNDATION
Different workloads.
One compute foundation.
AI workloads place very different demands on compute, networking, storage, security and operations. AALTA Infrastructure is designed so each environment can be configured around the workload without fragmenting the underlying platform.
01
FRONTIER MODEL TRAINING
Large-scale training environments designed for sustained GPU utilization, long-running workloads and high-bandwidth communication between compute nodes.
KEY NEEDS
Sustained GPU capacity
High-speed interconnect
High-throughput storage
Long-running workload stability
02
LARGE-SCALE INFERENCE
Production infrastructure optimized for predictable response times, high request volumes and continuous model serving.
KEY NEEDS
Low-latency compute
Elastic capacity
Reliable networking
Production availability
03
PRIVATE AI INFRASTRUCTURE
Dedicated environments for organizations that need greater control over data, infrastructure and workload isolation.
KEY NEEDS
Dedicated infrastructure
Controlled data environments
Workload isolation
Operational visibility
04
GPU CAPACITY EXPANSION
Infrastructure designed to grow incrementally as compute demand increases without rebuilding the underlying platform.
KEY NEEDS
Modular expansion
Power and cooling readiness
Network scalability
Operational continuity
01
FRONTIER MODEL TRAINING
Keep the GPUs working.
Training workloads depend on more than GPU count. Compute, network fabric, storage and facility infrastructure need to operate as one system to sustain utilization across long-running jobs.

02 / LARGE-SCALE INFERENCE
Infrastructure for models in production.
Inference environments need consistent performance as demand changes. AALTA Infrastructure supports dedicated production capacity designed around latency, availability and operational control.

03 / PRIVATE AI INFRASTRUCTURE
Control stays inside the environment.
For sensitive workloads, infrastructure boundaries matter. Dedicated environments allow organizations to maintain greater control over compute, data and operational access.
Dedicated capacity
Workload isolation
Controlled access
Data locality

04 / GPU CAPACITY EXPANSION
Grow capacity without rebuilding the foundation.
Compute requirements change over time. A modular infrastructure model allows additional GPU capacity to be introduced while preserving the surrounding network, facility and operational architecture.

INFRASTRUCTURE ALIGNMENT
Different workloads place pressure on different parts of the system.
Qualitative priorities show where each workload places its strongest demands. Every environment still depends on a shared operational foundation.
TRAINING
INFERENCE
PRIVATE AI
CAPACITY EXPANSION
GPU Compute
Core requirement
High priority
Core requirement
Core requirement
Networking
Core requirement
High priority
High priority
High priority
Storage
Core requirement
Workload dependent
Core requirement
Shared foundation
Power
Shared foundation
Shared foundation
Shared foundation
Core requirement
Cooling
Shared foundation
Shared foundation
Shared foundation
Core requirement
Security / Isolation
Workload dependent
Workload dependent
Core requirement
Shared foundation
Operational Control
High priority
Core requirement
Core requirement
Core requirement
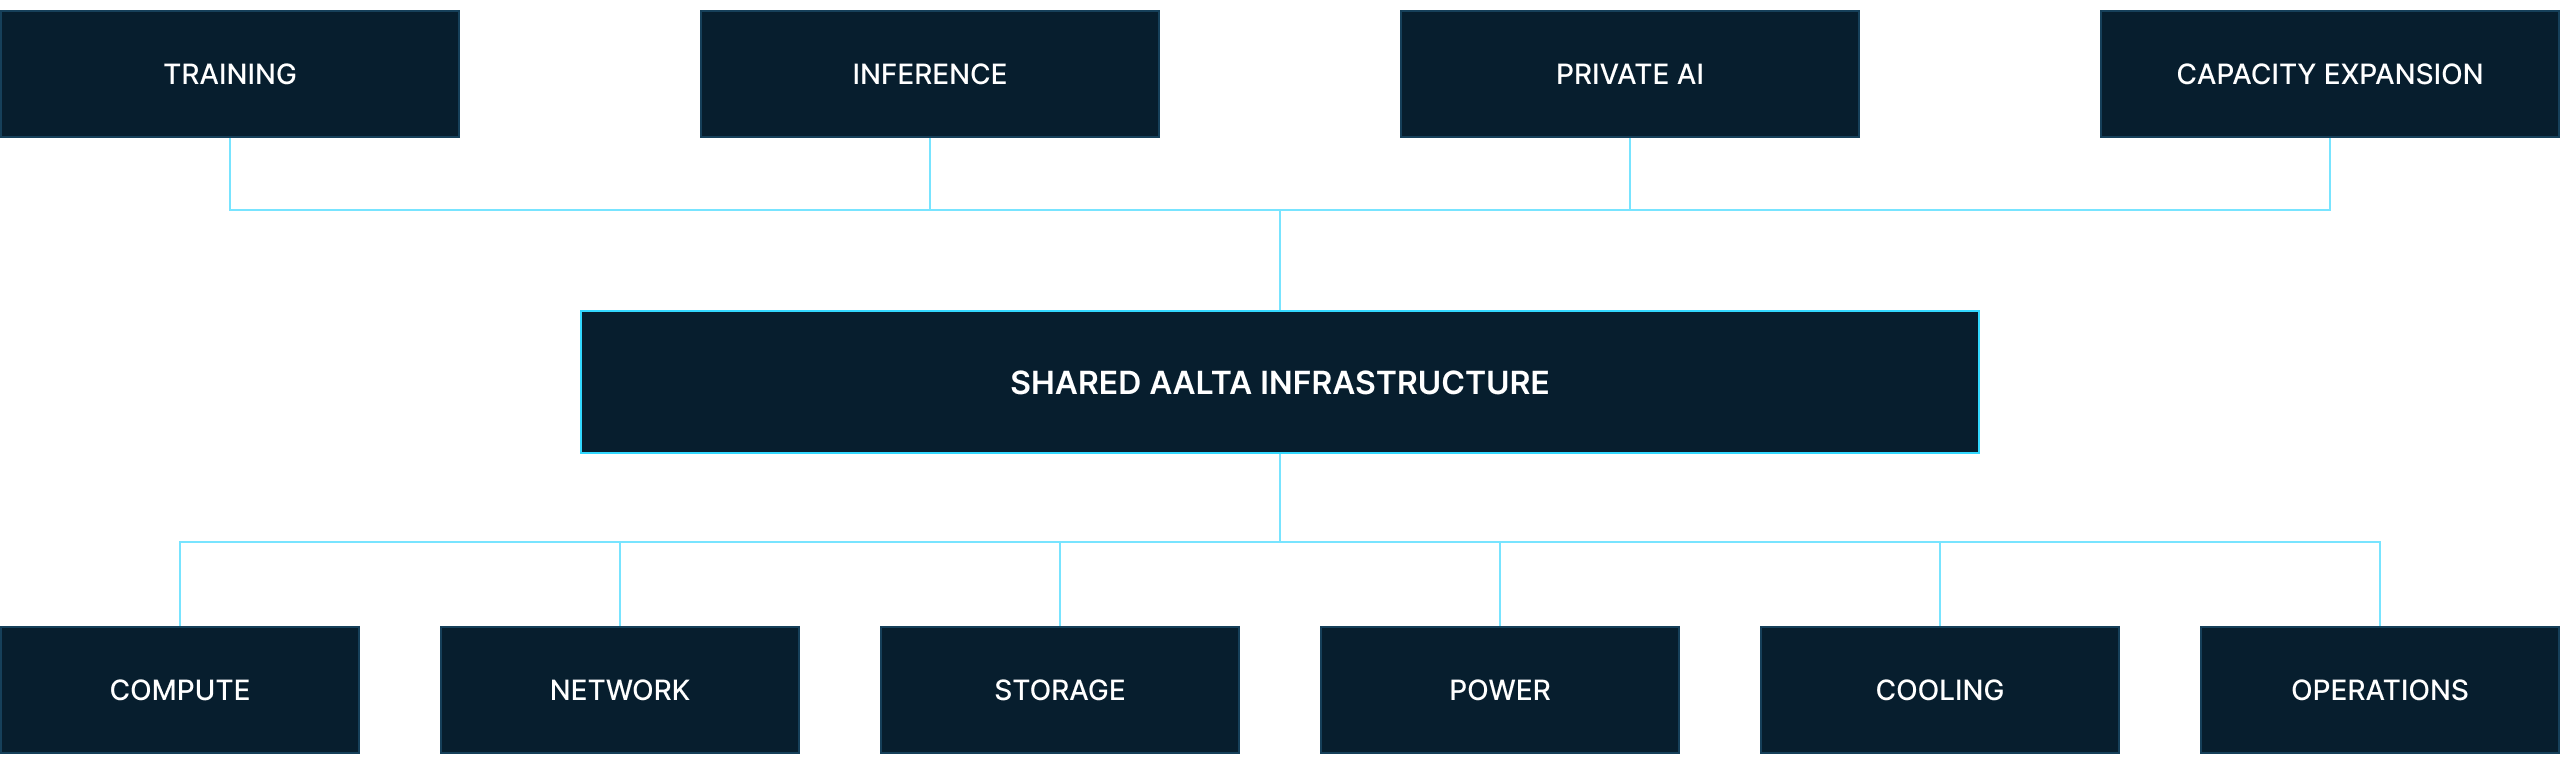
SHARED INFRASTRUCTURE FOUNDATION
The workload changes.
The foundation stays coherent.
Training, inference, private AI and capacity growth connect to one coordinated infrastructure platform.
PLAN YOUR INFRASTRUCTURE
Tell us what you need to run.
Whether the requirement is training, inference, private infrastructure or future GPU growth, we can help define the infrastructure around the workload.